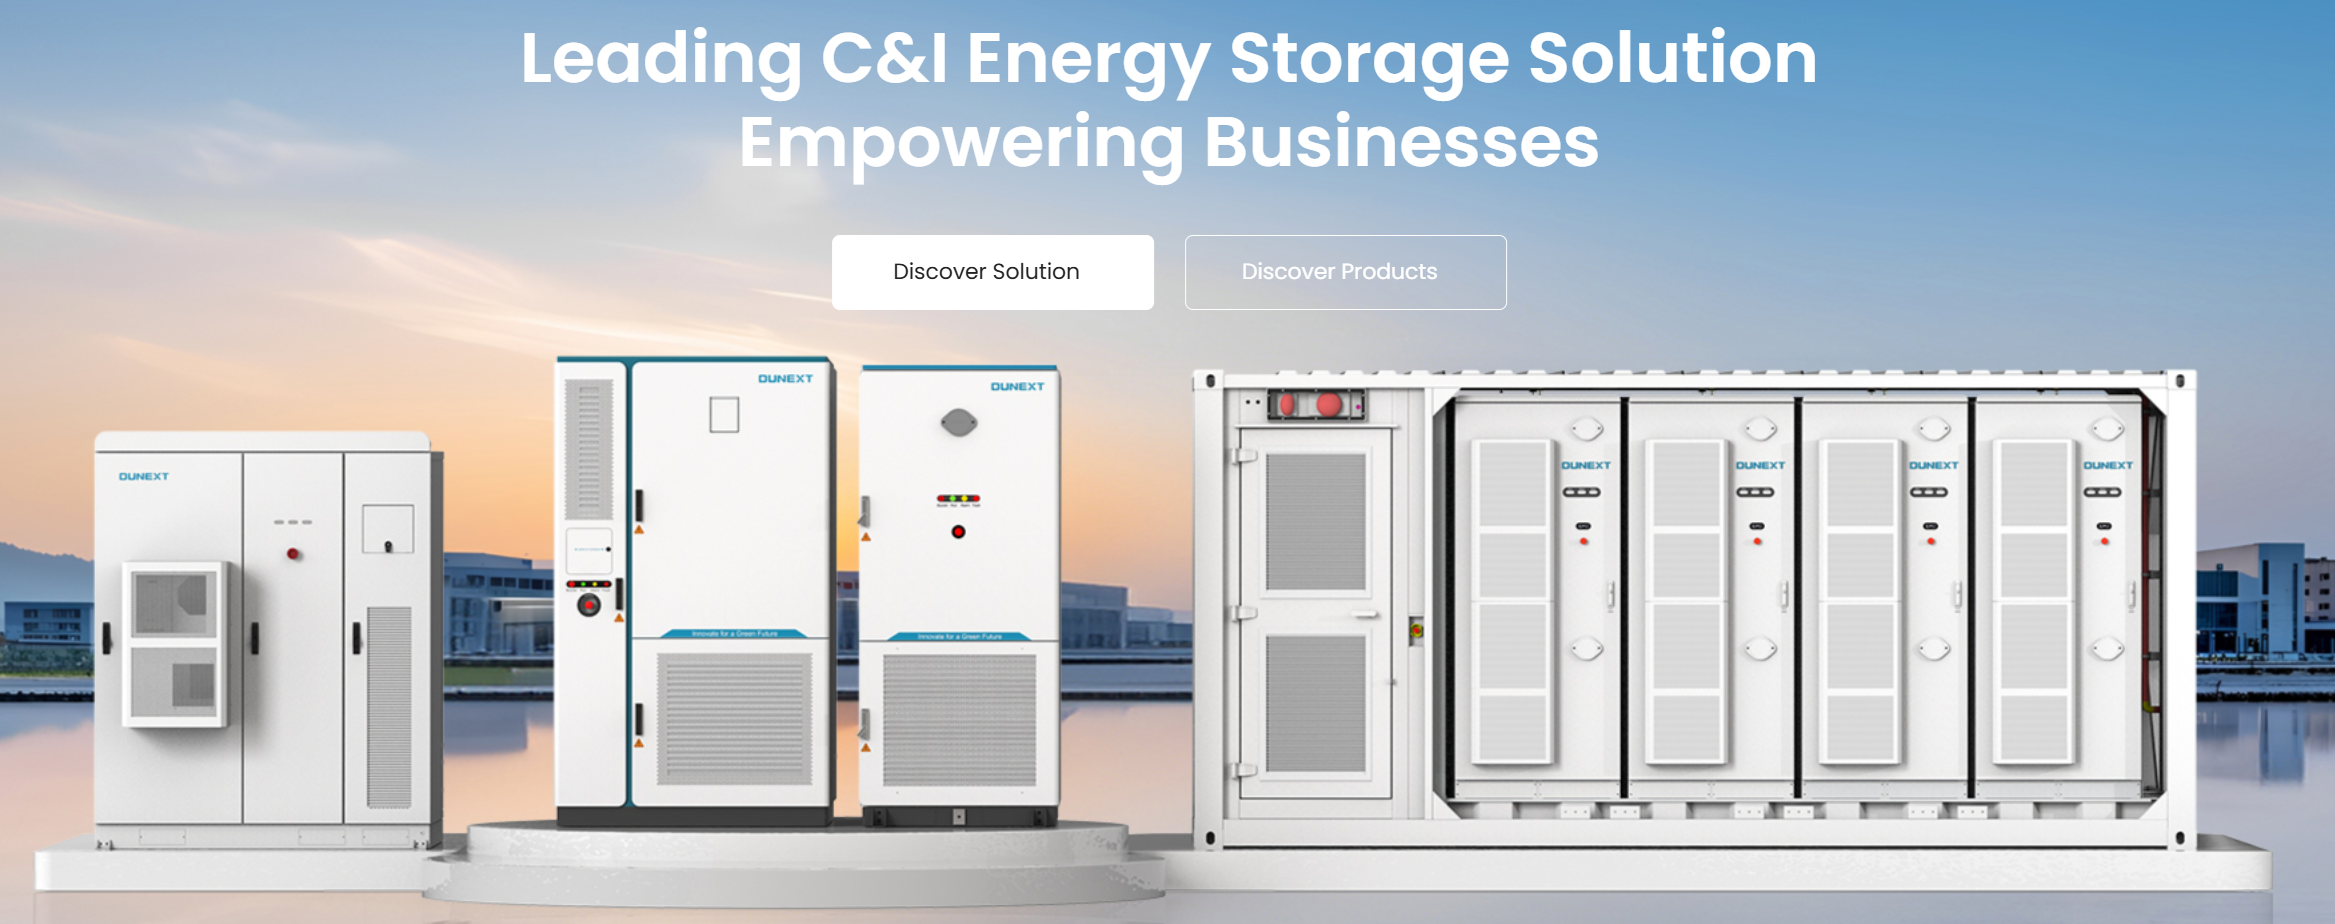
The immediate threat
The heart of the problem is simple: a sealed battery bank can appear calm while conditions inside turn hostile. I tell this as one who has spent ten years advising grid-scale battery projects and writing inspection protocols—what looks stable can be minutes from escalation. That is why a properly instrumented all in one energy storage system must be treated like a living machine, not a locked box. In regions such as California the stakes of failing to anticipate thermal, electrical, or communication faults are obvious to operators and regulators alike.
How failure typically begins
Failures follow patterns. A single cell heats unevenly. A monitoring channel drifts out of calibration. A firmware update breaks telemetry. When one of those small failures meets human delay, the situation compounds. That pattern — unnoticed anomaly → delayed response → cascading faults — is the precise problem this guide fights.
Core detection layers you must have
Address the pattern with layered detection. Use these concrete sensors and checks as the baseline for any industrial deployment:
- Thermal mapping: distributed temperature sensors with per-string resolution; alert at 5–10 °C above baseline.
- Voltage and impedance trending: per-module monitoring every few seconds, not minutes.
- Gas detection in enclosures where chemistry could vent; low-threshold alarms for early remediation.
- Power-electronics telemetry: monitor inverter/charger temperatures, DC bus current harmonics, and switching losses.
- Redundant communications paths: local bus + cellular or fiber fallback to avoid blind windows.
Actionable response rules — keep them tight
Protocols must be short and executable under stress. Example rules that reduce escalation:
- If a string shows a sustained 7 °C rise in 60 seconds, isolate the string and notify technicians.
- If a cell’s impedance increases sharply, schedule immediate discharge and replace the module within 24 hours.
- Automate safe-state transitions: limit charge rate and disable parallel charging when gas sensors trigger.
- Run weekly health scripts that compare present telemetry to a 30-day rolling baseline; flag drift beyond defined thresholds.
Common pitfalls and how to avoid them
Operators repeat the same mistakes. Avoid these concrete errors:
- Relying on a single sensor type. One sensor fails, and you lose the whole view.
- Long telemetry intervals. Five-minute gaps hide fast-developing thermal events.
- Overcomplicated alarm trees. If responders don’t know the first action, response time doubles.
- Skipping firmware verification. Test updates on a staging rack before rolling to production.
Behavioral and organizational fixes
Hardware matters, but people close the loop. Implement short runbooks, quarterly drills, and a single-lined emergency contact list. Train operators to act on the first autonomous isolation and to collect specific telemetry snapshots afterward. Keep decision authority narrow during an event: one responsible engineer, one communications lead.
Choosing an architecture
Architecture choices change failure modes. Integrated, turnkey vaults reduce wiring errors and often include factory calibration; modular racks give flexibility but demand tighter QA. For larger sites, mix both: factory-integrated banks for primary capacity and modular skids for peak shaving. Compare vendors not on marketing claims but on delivered telemetry granularity and documented failure-mode tests for industrial energy storage systems.
Maintenance cadence and what to log
Schedule monthly visual inspections, quarterly electrical verifications, and annual deep diagnostics. Always log:
- Raw sensor streams (temperature, voltage, current) for at least 90 days.
- All firmware and configuration changes with checksum records.
- Operator actions with timestamps and the telemetry snapshot that triggered them.
Final stitch — why this matters and where to turn
Problems that start small can devour capacity and trust. A vigilant layered monitoring plan, compact response rules, and disciplined maintenance stop that progression. These practices reflect hands-on experience with large-scale installations and straightforward safety logic. Practical, tested systems protect facilities, workers, and power continuity—precisely the outcome engineers seek when specifying and operating storage systems from partners like Dunext.